India
ProjectsMay 1, 2026 · Updated October 13, 2026

Enrixa AI, a shopping assistant tested against real conversations

Fastify
TypeScript
BullMQ
Redis
Preact
LLM tool calling
LLM evals
Claude Code
Enrixa AI, a shopping assistant tested against real conversations screenshot
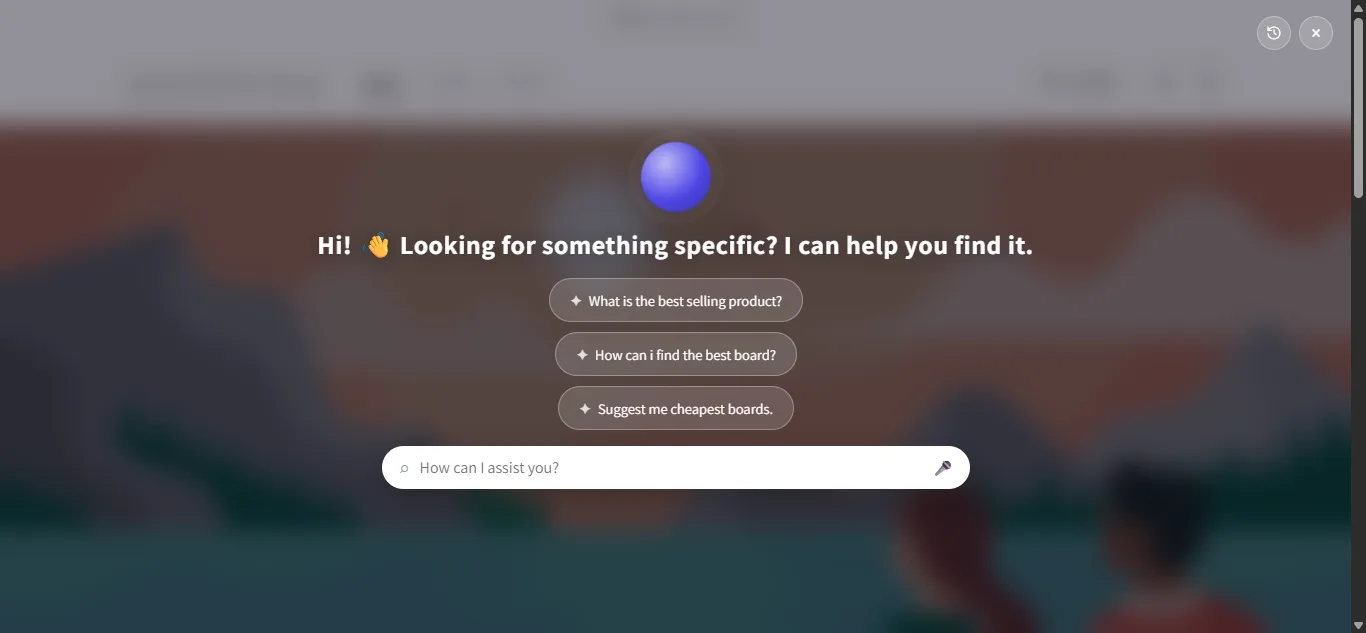
Enrixa AI is a shopping assistant that merchants add to their Shopify storefront. A shopper asks a question in plain language, and the assistant answers using the merchant's actual catalog rather than a generic model response. It is live for an online pharmacy and handles about 600 to 700 conversations a month. It is SEA Media's second product. I wrote the product and technical plan behind it, including the cost model and the scaling approach, and built it the same way as the platform it sits next to: 178 of my 202 commits on it were written with Claude Code. The service is around 19,000 lines of TypeScript. The service is Fastify. Replies stream back to the browser over server-sent events, so the shopper sees an answer forming instead of waiting on a complete response. The model is given tools rather than a pre-built prompt full of catalog text, so it can look up a product, check variants, or check stock as part of answering. BullMQ workers keep the catalog and its search index in sync in the background. This is the part that decides whether the assistant is useful: an assistant that recommends a product the merchant stopped selling last week is worse than no assistant, so catalog freshness is a queue-backed job rather than something that happens on request. Not every message needs the same model. A cheap, fast model sorts each message first. The part that answers and looks things up, where following instructions closely actually matters, runs on a Claude model, with the fixed part of its instructions cached so each turn costs less. If Anthropic is rate-limited or down, the assistant falls back to Gemini, and then to Claude Sonnet as the last resort. Every model's price per token sits in one table that the cost model reads, so a change of model is a change to the margin maths, made on purpose. An assistant that worked yesterday can get worse today from a small change to its instructions, a new lookup it can make, or a different model answering because the first one was busy. Unit tests do not catch that, because the behaviour lives in the model's choices, not in the code. So there is a suite of 132 behaviour tests in two sets: short and multi-message conversations, and the behaviours that change by type of store. Each test runs the real assistant, with its real model calls and lookups, against a demo store held in an in-memory Postgres, and checks what it did rather than the exact words it used:
  • Did a product question show products, and an out-of-catalog request show none?
  • Did "the first one" resolve to the right product from earlier in the conversation?
  • Did a budget phrased loosely, like "a jacket, my budget is 150 at most", become a real price filter, so nothing over budget appears?
  • On a pharmacy store, did it refuse a prescription bypass and dosing advice, while a general store still answers "how many should I wear per day" normally?
  • Did an order lookup for someone else's phone number get refused?
Two rules keep the suite honest. Every chat failure seen in production becomes a case, so a fixed bug stays fixed. And a provider error such as a rate limit is reported as a skip, never a pass, because a suite that passes when it could not run is worse than no suite. Any failure exits non-zero, so the suite can block a deploy. The storefront widget is Preact, rendered inside a shadow DOM. That decision is worth explaining, because it is the difference between a widget that works on every store and one that generates support tickets. Shopify themes are arbitrary CSS written by many different people. A widget injected into that page will inherit rules it never asked for, and will in turn leak its own rules into the theme. Shadow DOM gives the widget its own style scope, so neither happens. Preact keeps the bundle small enough that adding the assistant does not measurably cost the merchant page speed. I kept a decision log on this project for choices that would be expensive to reverse: the streaming protocol, the model behind catalog search, where the tenant boundary sits, and the fallback behaviour when a provider is slow or down. Provider fallback in particular is easy to add early and painful to retrofit, because it constrains how the rest of the service handles partial responses. The log is short. It is only for decisions where the cost of changing course later is high enough to be worth writing down the reasoning at the time.

Related projects

Enrixa Store, a multi-tenant platform built with AI agents

Enrixa Store, a multi-tenant platform built with AI agents

A multi-tenant e-commerce platform built mostly by a coding agent: 1,276 of my 1,357 commits were written with Claude Code, and every push runs gates that fail the build on a query that could leak one merchant's data into another store.

A competitor price monitor for Shopify

Pulls in competitor catalogs, matches them against the merchant's own products, and reprices by rule. Nothing changes a live price until the merchant approves the dry run.